Published Android app
LODORi
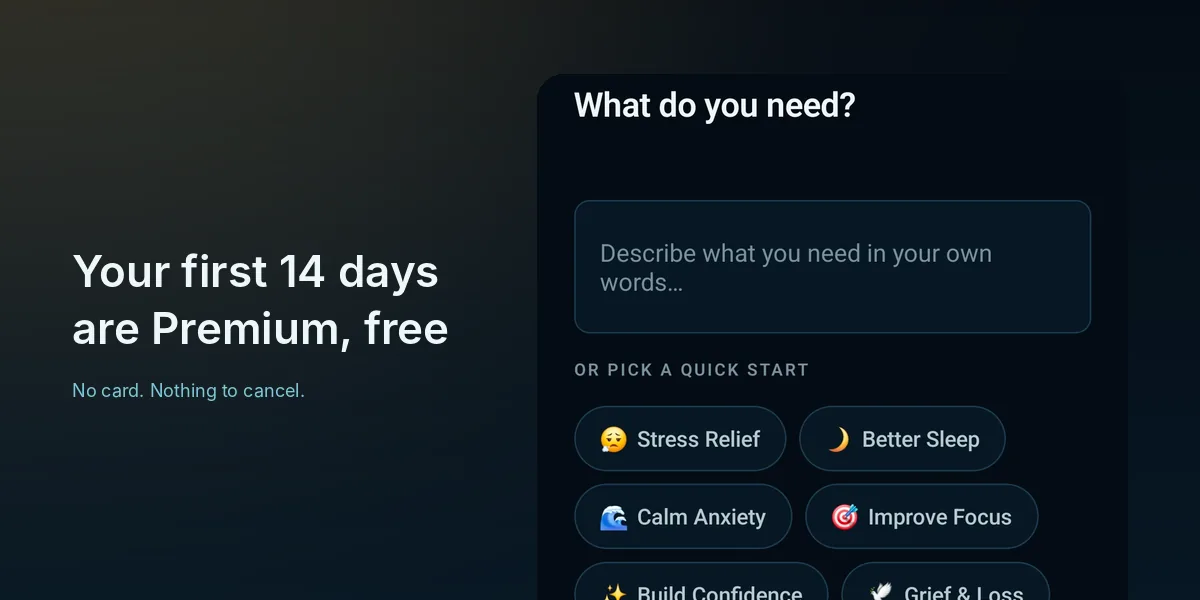
A meditation app that writes and voices a personalised session in about 25 seconds. React Native, FastAPI, subscriptions, ads, safety checks, and a public release on Google Play.
 LMC Tech
Our work / Text-to-film pipeline
A film pipeline that runs unattended on a self-hosted GPU. A language model writes the story and shot list, image models produce keyframes with characters that stay the same across scenes, a vision model rejects the bad ones, a video model adds motion and sound, a voice reads the narration, ffmpeg cuts it. You get a contact sheet after twenty minutes so a bad film is caught early.
The brief
Short-form video is cheap to consume and expensive to make. The hard part of AI film is not one pretty frame, it is the same face in shot seven as in shot one, and a pipeline that survives a crash at 2am.
Under the bonnet
Qwen3 on Ollama for writing, Flux 2 for keyframes and reference portraits, Gemma 3 vision for QA, LTX 2.3 for motion with native synced audio, Piper for narration, ComfyUI as the model host and ffmpeg for the edit, all on an Ubuntu box with an RTX 3060. Systemd path units run the queue.
What it shows
A meditation app that writes and voices a personalised session in about 25 seconds. React Native, FastAPI, subscriptions, ads, safety checks, and a public release on Google Play.
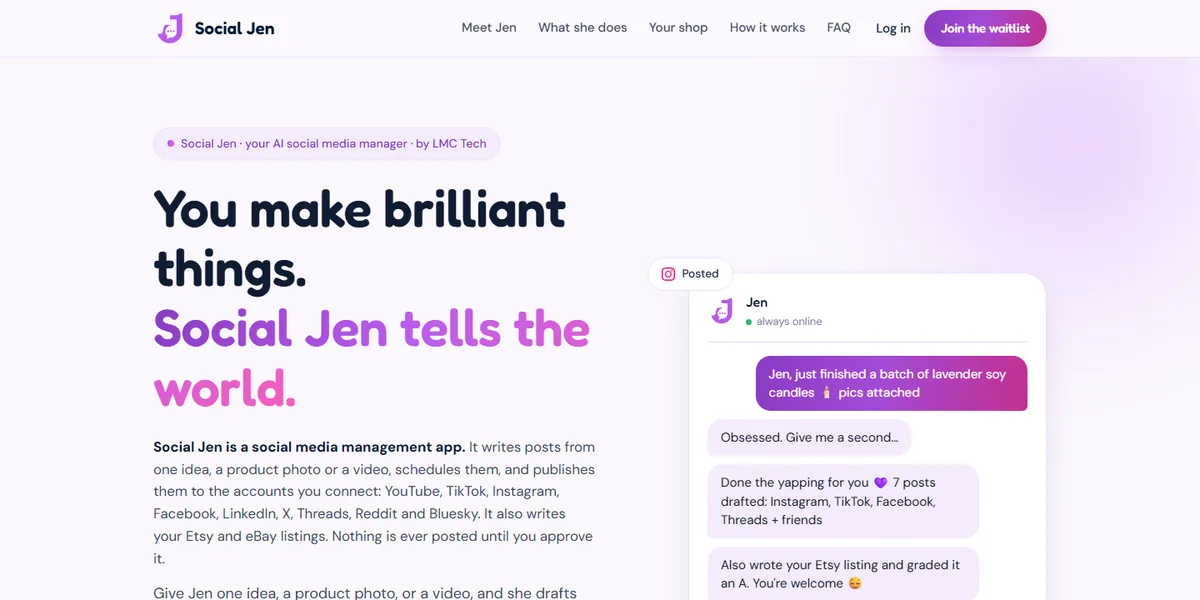
Give it one idea, a product photo or a video and it drafts, schedules and publishes to nine social networks, writes graded Etsy listings and renders your 3D models. Nothing goes out until you approve it.
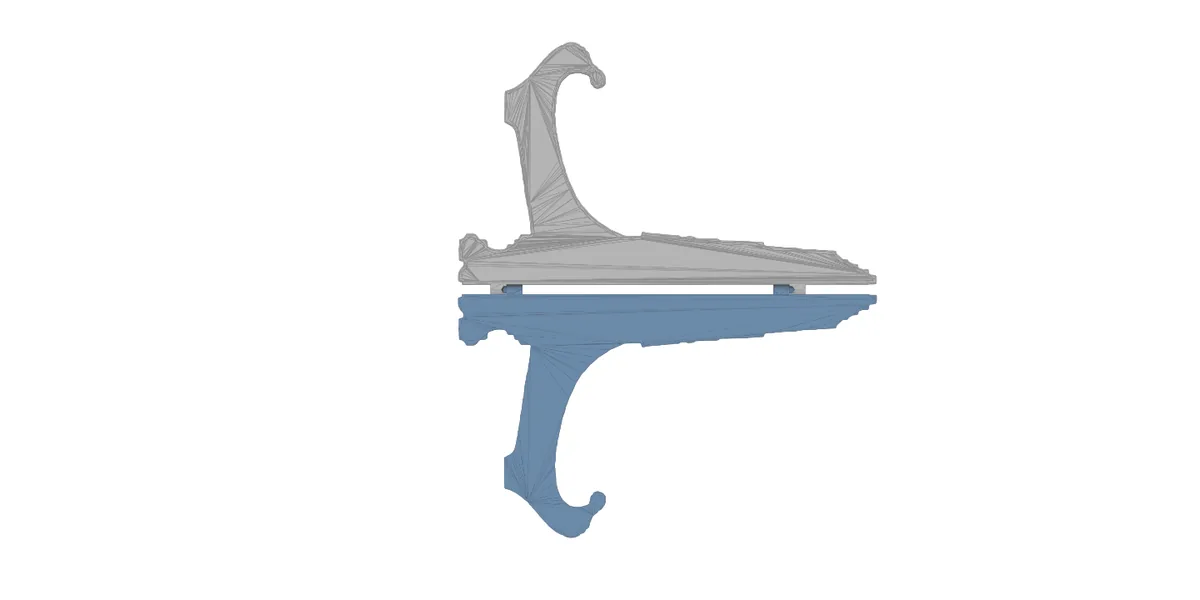
Describe a part or drop in a picture and get a watertight, print-ready STL. Exact parametric CAD written by a language model, or organic meshes from AI, both validated before a slicer ever sees them.
Next step